Thursday, 3 February 2022

How to Monitor PostgreSQL Connections

 How to identify and terminate connections that are lying idle and consuming resources.

  1. States of a connection
  2. Identifying the connection states and duration
  3. Identifying the connections that are not required
  4. Terminating a connection when necessary


In order to make modifications or read data from a PostgreSQL database, the first thing we need to do is to create connections. However, each connection comes with overhead in terms of both process and memory; hence a system with limited resources (read, hardware)  can only handle a certain number of connections. Once it goes beyond that, it will start throwing errors or refusing connections. PostgreSQL does a good job restricting the connections in postgresql.conf.

In this post we will look at the types of states that exist for connections in PostgreSQL. We will show how to find out if that connection is doing work or has been lying idle for a period of time, in which case it should be terminated to recover the connection and resources. We will go through the following steps:

  1. Understanding the states of a connection
  2. Identifying the states and duration of the current connections
  3. Identifying the connections that are not required
  4. Terminating a connection when necessary


1. States of a connection

Once a connection in PostgreSQL is created, it can perform various operations that lead to changes in states. Based on the state and the time the connection has been in that state, an informed decision can be made as to whether the connection is active or has been left idle/abandoned. 

It is worth mentioning that if the connection is not explicitly closed by the application, it will remain available, thereby consuming resources—even when the client has disconnected.

These are the four states a connection can have:

  1. active: This indicates that the connection is working. 
  2. idle: This indicates that the connection is idle and we need to track these connections based on the time that they have been idle.
  3. idle in transaction: This indicates the backend is in a transaction, but it is currently not doing anything and could be waiting for an input from the end user.
  4. idle in transaction (aborted): This state is similar to idle in transaction, except one of the statements in the transaction caused an error. This also needs to be monitored based on the time since it has been idle.


2. Identifying the connection states and duration

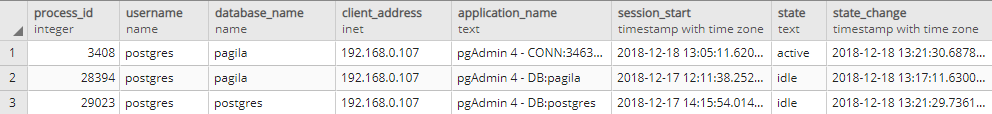
The pg_stat_activity view in the PostgreSQL catalog tables gives you information regarding what a connection is doing and how long it has been in that state. If you run the query to get the values from the view, you get the following output for the state of each connection:

How to Monitor PostgreSQL Connections


From the above output the one value which we are looking for is the “state”. We can use that to find out which queries are in which state and then we can dig further. So, we can modify the query to show specific records related to just the queries which are idle:

Select * from pg_stat_activity where state=’idle’;


3. Identifying the connections that are not required

We can modify the query a bit more to narrow down the information we are looking for so that we can plan an action on that particular connection. We can do this by selecting just the PIDs and the query states for the PIDs that are idle. We also need to monitor the time since the connection has been idle to check that we do not have any abandoned connections wasting our resources as well. So this would mean:

Select pid, usename, application_name, backend_start, state_change, state from pg_stat_activity where state=’idle’;


4. Terminating a connection when necessary

Once we have narrowed down the query that is either in a hang state or has been idle for a long time, we can use this query to simply kill the backend process without affecting the operations of the server:

SELECT pg_terminate_backend(PID);


database sessions query

Query

select pid as process_id, 
       usename as username, 
       datname as database_name, 
       client_addr as client_address, 
       application_name,
       backend_start,
       state,
       state_change
from pg_stat_activity;

Columns

  • process_id - process ID of this backend
  • username - name of the user logged into this backend
  • database_name - name of the database this backend is connected to
  • client_address - IP address of the client connected to this backend
  • application_name - name of the application that is connected to this backend
  • backend_start - time when this process was started. For client backends, this is the time the client connected to the server.
  • state - current overall state of this backend. Possible values are:
    • active
    • idle
    • idle in transaction
    • idle in transaction (aborted)
    • fastpath function call
    • disabled
  • state_change - time when the state was last changed

Rows

  • One row: represents one active connection
  • Scope of rows: all active connections

Sample results

You can see session list on our test server.

sample results

CREATE CLUSTER


[root@postgres Desktop]# cd /data1/

[root@postgres data1]# mkdir prod
[root@postgres data1]# chown postgres:postgres prod/ -R

[root@postgres data1]# su - postgres

-bash-4.1$ initdb -D /data1/prod/ ---------------> starting new cluster instance 

-bash-4.1$ cd /data1/prod/
-bash-4.1$ vi postgresql.conf

port=5433

:wq

-bash-4.1$ pg_ctl -D /data1/prod/ start ---------------------> starting database

-bash-4.1$ ps -ef | grep postgres
root     17715 17705  0 13:51 pts/0    00:00:00 su - postgres
postgres 17716 17715  0 13:51 pts/0    00:00:00 -bash
postgres 17783     1  0 13:53 pts/1    00:00:00 /opt/PostgreSQL/10/bin/postgres -D ../data
postgres 17784 17783  0 13:53 ?        00:00:00 postgres: logger process                  
postgres 17786 17783  0 13:53 ?        00:00:00 postgres: checkpointer process            
postgres 17787 17783  0 13:53 ?        00:00:00 postgres: writer process                  
postgres 17788 17783  0 13:53 ?        00:00:00 postgres: wal writer process              
postgres 17789 17783  0 13:53 ?        00:00:00 postgres: autovacuum launcher process     
postgres 17790 17783  0 13:53 ?        00:00:00 postgres: stats collector process         
postgres 17791 17783  0 13:53 ?        00:00:00 postgres: bgworker: logical replication launcher   
root     17832 17741  0 13:59 pts/1    00:00:00 su - postgres
postgres 17833 17832  0 13:59 pts/1    00:00:00 -bash
postgres 17890     1  0 14:01 pts/1    00:00:00 /opt/PostgreSQL/10/bin/postgres -D /data1/prod
postgres 17892 17890  0 14:01 ?        00:00:00 postgres: checkpointer process                     
postgres 17893 17890  0 14:01 ?        00:00:00 postgres: writer process                           
postgres 17894 17890  0 14:01 ?        00:00:00 postgres: wal writer process                       
postgres 17895 17890  0 14:01 ?        00:00:00 postgres: autovacuum launcher process              
postgres 17896 17890  0 14:01 ?        00:00:00 postgres: stats collector process                  
postgres 17897 17890  0 14:01 ?        00:00:00 postgres: bgworker: logical replication launcher   

-bash-4.1$ psql -p 5433 -U postgres -d postgres
psql.bin (10.9)
Type "help" for help.

postgres=# show data_directory;
  data_directory  
------------------
 /data1/prod
(1 row)

postgres=# show port;
 port 
------
 5433
(1 row)

postgres=# select datname from pg_database;
  datname  
-----------
 postgres
 template1
 template0
(3 rows)

postgres=# 

postgres=# create table emp(name char);
CREATE TABLE
postgres=# insert into emp values('s');
INSERT 0 1
postgres=# \dt
        List of relations
 Schema | Name | Type  |  Owner   
--------+------+-------+----------
 public | emp  | table | postgres
(1 row)

postgres=# \dt+
                      List of relations
 Schema | Name | Type  |  Owner   |    Size    | Description 
--------+------+-------+----------+------------+-------------
 public | emp  | table | postgres | 8192 bytes | 
(1 row)

PostgreSQL Basic Query1

-bash-4.1$ ./psql -p 5435 -U postgres -d postgres ---------------------
psql.bin (9.6.8)
Type "help" for help.

postgres=# show data_directory;
         data_directory          
---------------------------------
 /opt/PostgreSQL/9.6/bin/../data
(1 row)

postgres=# select current_user;
 current_user 
--------------
 postgres
(1 row)

postgres=# select version();
                                                 version                                                  
----------------------------------------------------------------------------------------------------------
 PostgreSQL 9.6.8 on x86_64-pc-linux-gnu, compiled by gcc (GCC) 4.4.7 20120313 (Red Hat 4.4.7-16), 64-bit
(1 row)

postgres=# select datname from pg_database;
      datname       
--------------------
 postgres
 template1
 template0
 contrib_regression
 db96
(5 rows)

postgres=# select pg_backend_pid();
 pg_backend_pid 
----------------
          15013 


Wednesday, 2 February 2022

Switchover and Switchback in PostgreSQL10


postgres=# select application_name, state, sync_priority, sync_state from pg_stat_replication;

 application_name |   state   | sync_priority | sync_state
------------------+-----------+---------------+------------
 walreceiver      | streaming |             0 | async


If Return  false so the server is running in Primary mode or Master


/u02/PostgreSQL/10/data
cat recovery.conf
standby_mode = 'on'
primary_conninfo = 'user=replicator password=replicator host=192.168.0.106 port=5432 sslmode=prefer sslcompression=1 krbsrvname=postgres target_session_attrs=any'
recovery_target_timeline = 'latest'
trigger_file = '/u02/PostgreSQL/10/data/recovery.stop'


Now run the touch the file  (2nd step main)

touch /u02/PostgreSQL/10/data/recovery.stop


Standby has been promoted as master and a new timeline followed which you can notice in logs.

 2020-03-26 20:46:34 IST    LOG:  trigger file found: /u02/PostgreSQL/10/data/recovery.stop
 2020-03-26 20:46:34 IST    LOG:  redo done at 0/2B000028
 2020-03-26 20:46:34 IST    LOG:  last completed transaction was at log time 2020-03-25 19:45:14.642094+05:30
 2020-03-26 20:46:34 IST    LOG:  selected new timeline ID: 2
 2020-03-26 20:46:34 IST    LOG:  archive recovery complete
 2020-03-26 20:46:34 IST    LOG:  checkpoint starting: force
 2020-03-26 20:46:34 IST    LOG:  database system is ready to accept connections
 2020-03-26 20:46:34 IST    LOG:  checkpoint complete: wrote 0 buffers (0.0%); 0 WAL file(s) added, 0 removed, 0 recycled; write=0.000 s, sync=0.000 s, total=0.028 s; sync files=0, longest=0.000 s, average=0.000 s; distance=0 kB, estimate=14702 kB


cat recovery.conf
recovery_target_timeline = 'latest'
standby_mode = 'on'
primary_conninfo = 'user=replicator password=replicator host=192.168.0.107 port=5432 sslmode=prefer sslcompression=1 krbsrvname=postgres target_session_attrs=any'
trigger_file = '/u02/PostgreSQL/10/data/recovery.stop'


Check the data in primary and standby:-


Setup Replication (Master — Slave Setup) on PostgreSQL10

Below are step by step implementation 

Step 1 - Install PostgreSQL 10

Step 2 - Start and configure PostgreSQL 10

Step 3 - Configure Firewalld

Step 4 - Configure Master server

Step 5 - Configure Slave server


NOTE: Run the Step 1, Step 2 and Step 3 on all Master and Slaves.


In this step, we will configure a master server for the replication. This is the main server, allowing read and write process from applications running on it. PostgreSQL on the master runs only on the '10.0.15.10' IP address, and performs streaming replication to the slave server.


1) => edit the configuration file 'postgresql.conf'

Uncomment the 'listen_addresses' line and change value of the server IP address to '192.168.0.108'.

listen_addresses = '*' or  '192.168.0.108' 

2) => Uncomment 'wal_level' line and change the value to 'hot_standby'.

wal_level = hot_standby

3) VIMP: For the synchronization level, we will use local sync. Uncomment and change value line as below.

synchronous_commit = local

4) Enable archiving mode and give the archive_command variable a command as value.

archive_mode = on
archive_command = 'cp %p /u02/PostgreSQL/archive/%f'

5) For the 'Replication' settings, uncomment the 'wal_sender' line and change value to 2 (in this tutorial,  we use only 2 servers master and slave), and for the 'wal_keep_segments' value is 10.

max_wal_senders = 2
wal_keep_segments = 10
hot_standby = on


6) For the application name, uncomment 'synchronous_standby_names' line and change value to 'pgslave01'.

synchronous_standby_names = 'pgslave01'


7) Moving on, in the postgresql.conf file, the archive mode is enabled, so we need to create a new directory for archiving purposes.

Create a new directory, change its permission, and change the owner to the postgres user.


mkdir -p /u02/PostgreSQL/archive
chmod 700 /u02/PostgreSQL/archive
chown -R postgres:postgres /u02/PostgreSQL/archive


8) Now edit the pg_hba.conf file.

vim pg_hba.conf

Paste configuration below to the end of the line.

# Localhost
 host    replication     replicator         127.0.0.1/32               md5

# PostgreSQL Master IP address
host    replication     replicator         192.168.0.108/32        md5


# PostgreSQL SLave IP address
 host    replication     replicator         192.168.0.107/32       md5


1) Note: Before we start to configure the slave server, stop the postgres service

2) Then go to the postgres directory, and backup data directory.

cd /u02/PostgreSQL/10
mv data data-backup


3) Create new data directory and change the ownership permissions of the directory to the postgres user.

mkdir -p data/
chmod 700 data/
chown -R postgres:postgres data/


4) Next, login as the postgres user and copy all data directory from the 'Master' server to the 'Slave' server as replica user.

pg_basebackup -h 192.168.0.106 -U replicator -p 5432 -D /u02/PostgreSQL/10/data -P -Xs -R


Please replace the IP address with your master’s IP address.


In the above command, you see an optional argument -R. When you pass -R, it automatically creates a recovery.conf  file that contains the role of the DB instance and the details of its master. 
It is mandatory to create the recovery.conf file on the slave in order to set up a streaming replication. 
If you are not using the backup type mentioned above, and choose to take a tar format backup on master that can be copied to slave, you must create this recovery.conf file manually. Here are the contents of the recovery.conf file:

Type your password and wait for data transfer from the master to the slave server.

32512/32512 kB (100%), 1/1 tablespace

5) After the transfer is complete, go to the postgres data directory and edit postgresql.conf file on the slave server.


Check and Change standby config file like below:

hot_standby = on
hot_standby_feedback=on


6) Then check and edit recovery.conf file and add lines below:


7) In the above file, the role of the server is defined by standby_mode. standby_mode  must be set to ON for slaves in postgres.
And to stream WAL data, details of the master server are configured using the parameter primary_conninfo .

The two parameters standby_mode  and primary_conninfo are automatically created when you use the optional argument -R while taking a pg_basebackup. This recovery.conf file must exist in the data directory($PGDATA) of Slave.


8) Now start the database server using pg_ctl command.

pg_ctl -D /u02/PostgreSQL/10/data start


Final Step 6- Validate that postgresql replication is setup

As discussed earlier, a wal sender  and a wal receiver  process are started on the master and the slave after setting up replication. Check for these processes on both master and slave using the following commands.

On Master
$ ps -eaf | grep sender


On Slave
$ ps -eaf | grep receiver
$ ps -eaf | grep startup


You can see more details by querying the master’s pg_stat_replication view.


Primary - Master :-

postgres=# select pg_is_in_recovery();
 pg_is_in_recovery
-------------------
 f


Standby - Slave :-

postgres=# select pg_is_in_recovery();
 pg_is_in_recovery
-------------------
 t


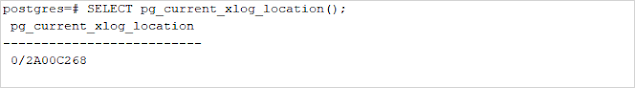
Master and Slave - Sync check - PostgreSQL

  1) Run the below Query on Primary:- SELECT     pid,     usename,     application_name,     client_addr,     state,     sync_state,     sen...